Colin Joy Lobo

Colin Joy
Lobo.

AI Engineer

I build the agentic systems behind generative film: multi-agent pipelines on Azure AI Foundry that turn a script into finished frames, the eval harnesses that catch their mistakes, and the inference that runs the whole thing. It's in production right now on streaming series and upcoming features.

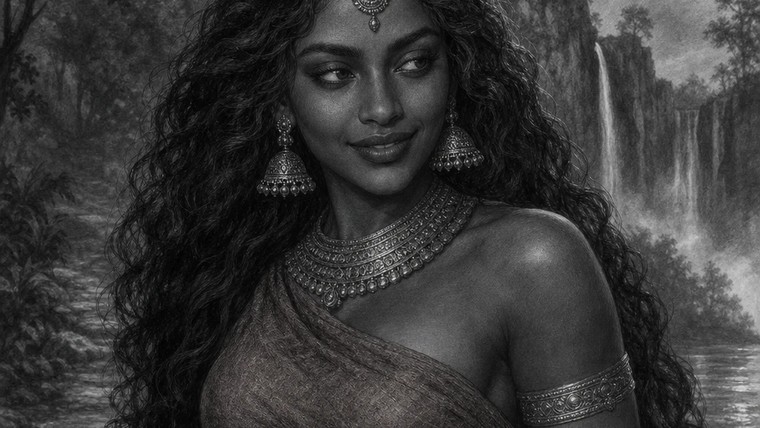
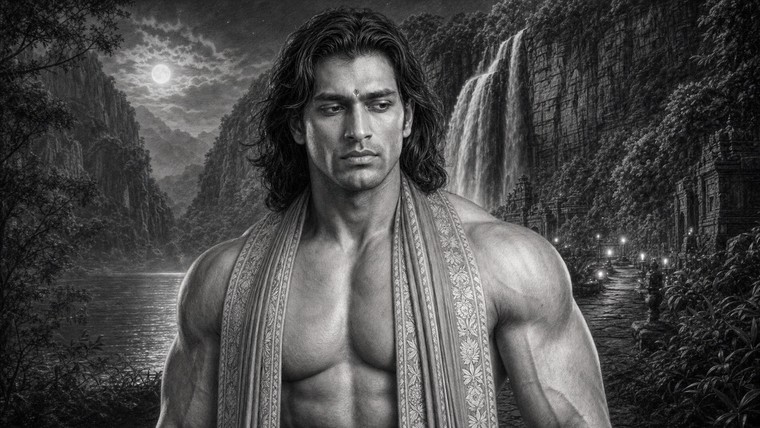
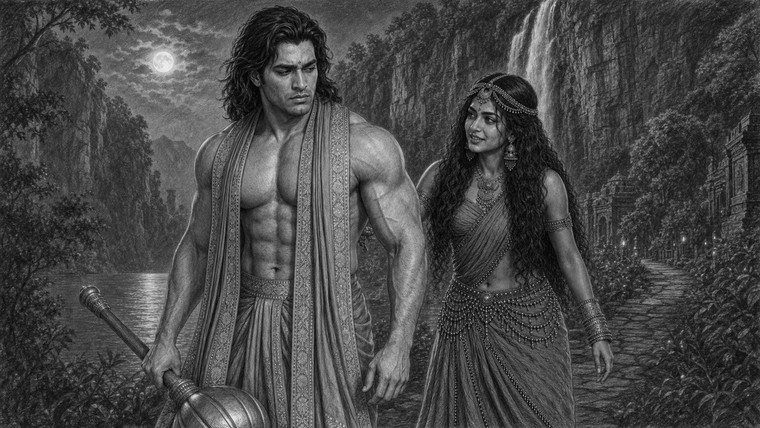
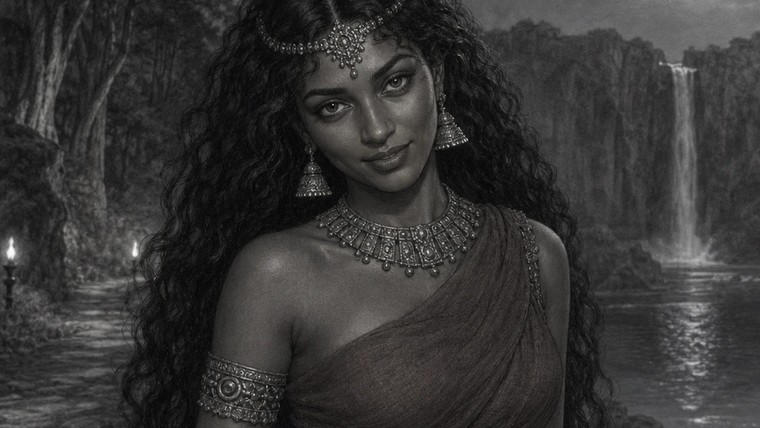
Real frames behind, from three productions.

Projects

Productions, tools & systems.

A In production
Watch trailer ↗
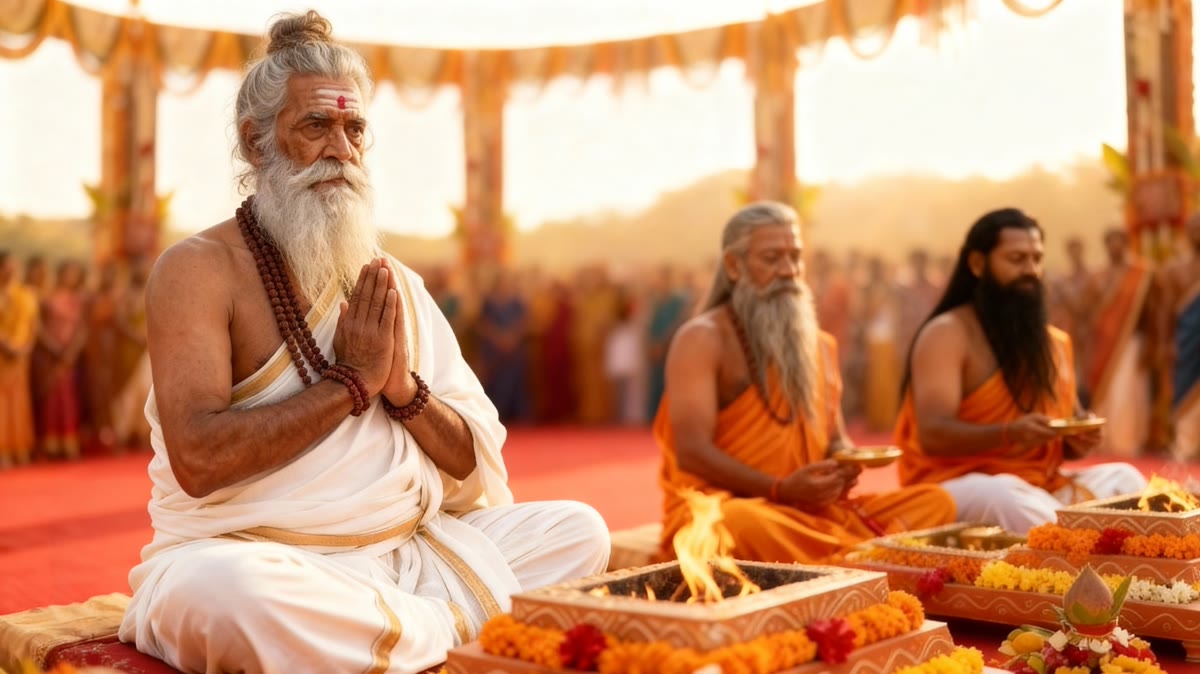
OTT productionJioHotstar

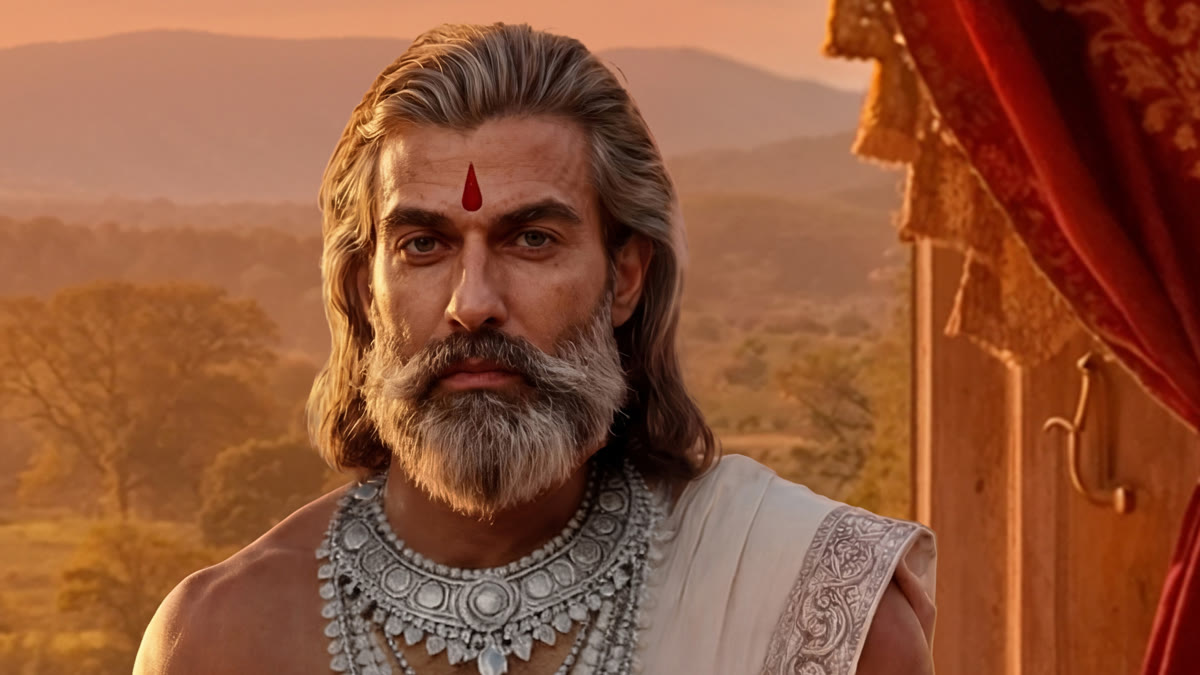
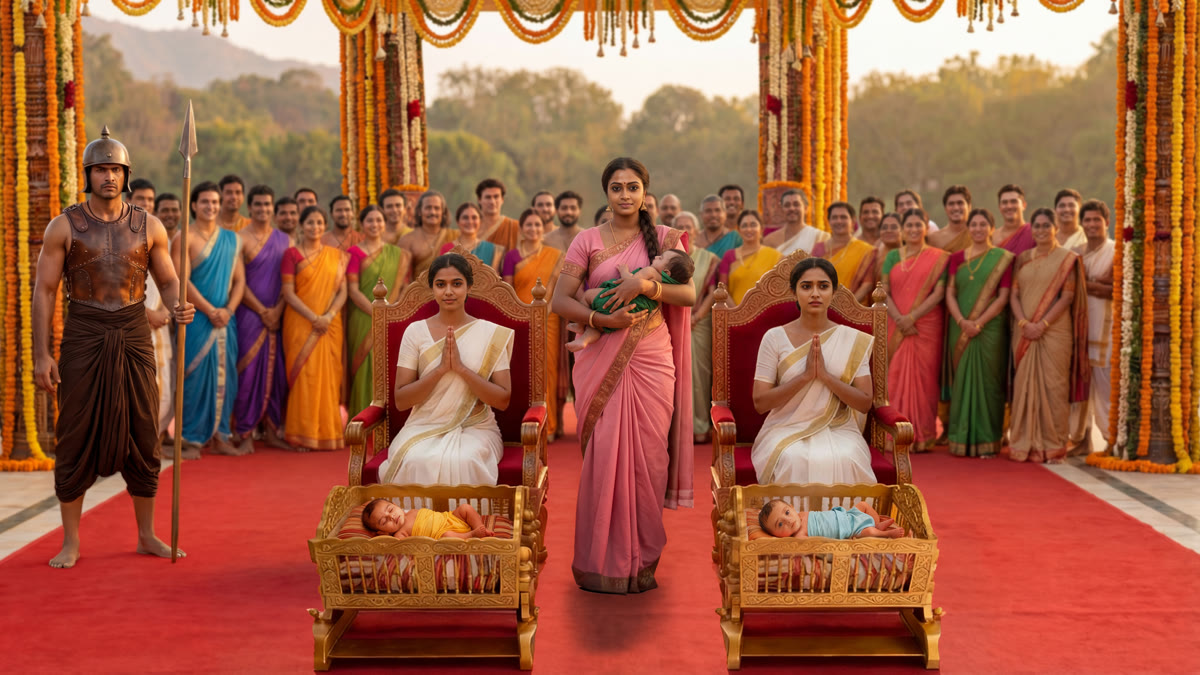
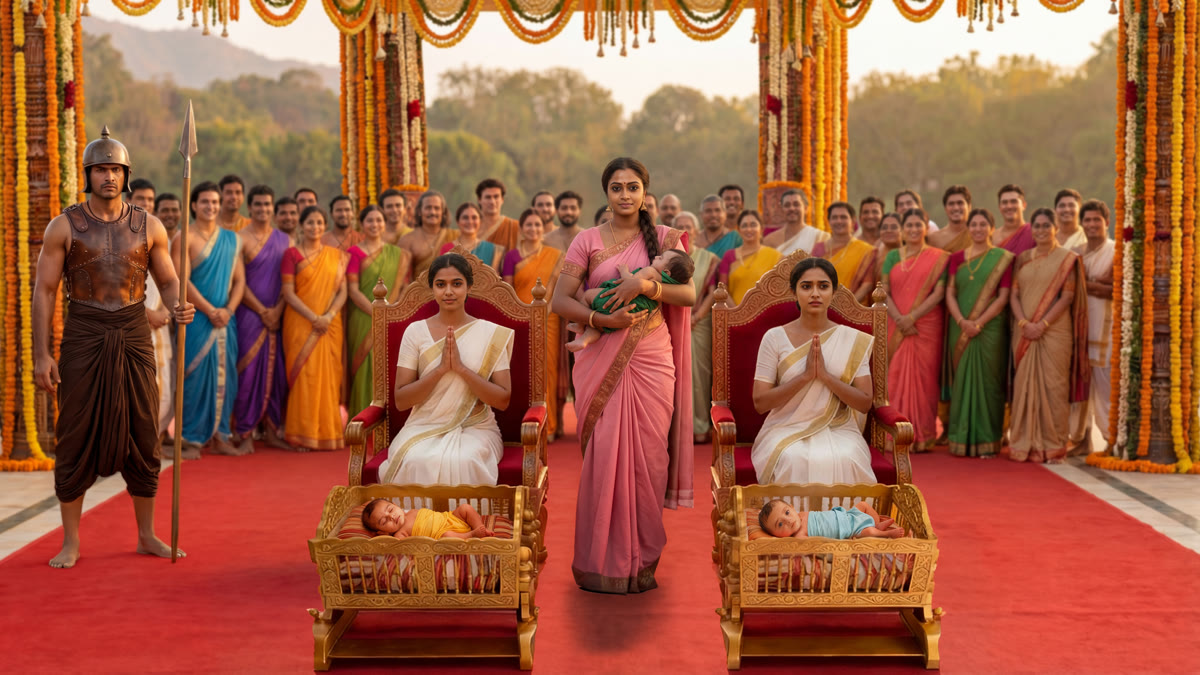
Mahabharat: Ek Dharmayudh

India's first AI-generated premium series, now past 26.5M views. I built the multi-agent shot pipeline behind it and the eval harness that gates every stage, running 50 to 200 generations a day at peak with 50+ artists downstream.
HistoryverseLipSyncCarveComfyUI
A generated frame from the Khana Dil Se cooking show
Watch on YouTube ↗
Food showYouTube

Khana Dil Se

Hansal Mehta's AI cooking show. I wrote the resumable runner that carries an episode's script to finished shots, 88 generated Bernini prompts for Ep04 alone, so a failed render retries without losing the batch. I also built the audio side: ElevenLabs generation and voice cloning, so one cloned voice carries the show across several languages instead of re-recording per language.

BerniniSeedance 2.0ElevenLabsVoice cloningMultilingual dub
Watch teaser ↗
Film VFXTheatrical, 2026

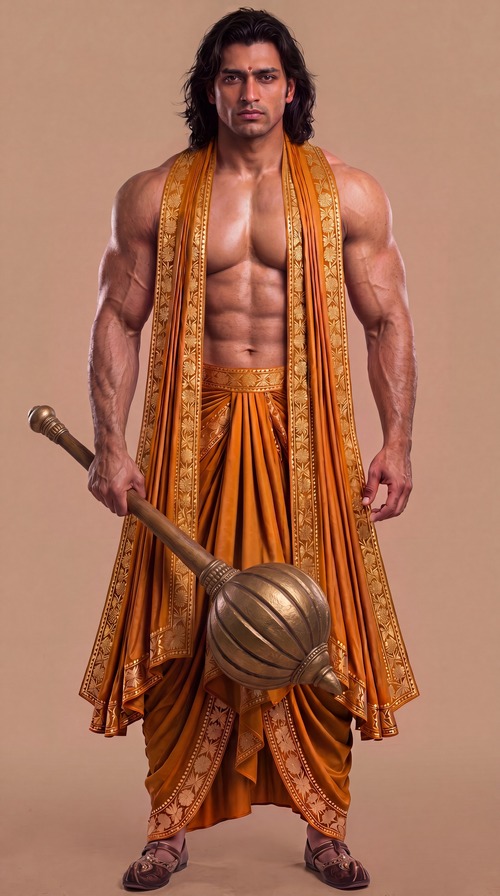
Chiranjeevi Hanuman: The Eternal

Storyboards and the image-to-3D pipeline for an AI-generated theatrical feature. Trellis meshes land at 1M+ faces with no materials, so they run through headless Blender retopology and texture baking before anything reaches a scene.

Image-to-3DStoryboard agentCueBlender
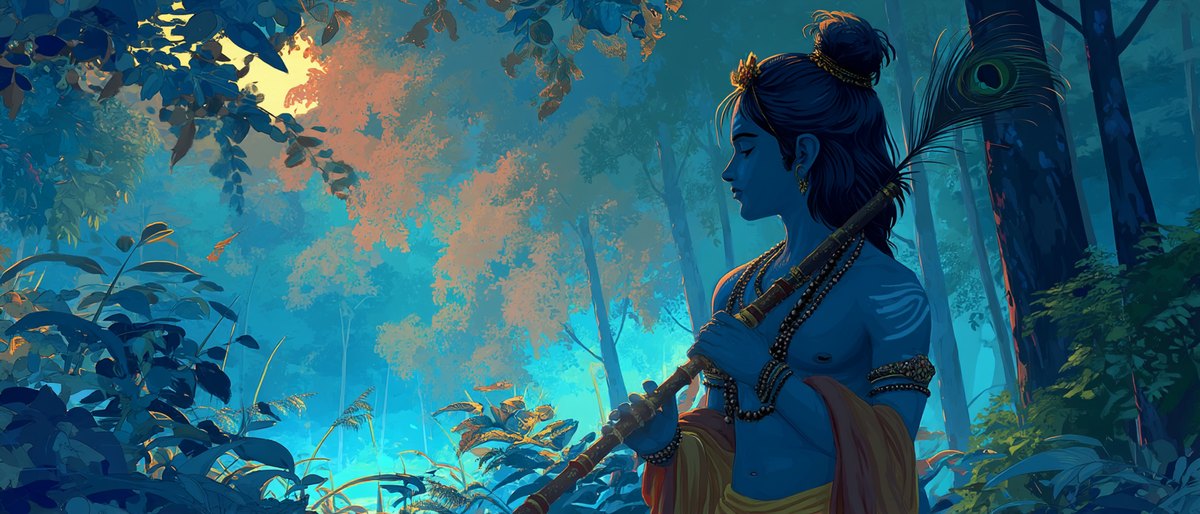
A cosmic concept frame from the Krishna feature
FilmIn production

Krishna

Storyboard generation and style transfer for an upcoming feature. Character LoRAs trained on Flux and SDXL with reference-image control hold likeness across hundreds of shots, which prompt text alone will not do over a film-length run.

HistoryverseCueStyle transfergpt-image-2
Instagram ↗
Celebrity techInstagram

Mishty, Rhea Chakraborty's AI avatar

A photoreal interactive avatar built on the studio pipeline: motion capture, isolated reference voice, and multi-character lip-sync held in sync across a full clip.

WanimateLipSyncVoice isolation
B Tools & systems
Multi-agentIn production

Six-agent creative pipeline

Six hosted agents carry a script to finished shot panels. Each hands a typed artifact to the next and is versioned in a registry, so a bad hand-off fails loudly instead of quietly corrupting the run. Tuning the judge was the real work: at threshold 0.5 it over-rejected pencil sketches for style bias and hallucinated absences. Dropping to 0.40 and telling it plainly that style is fixed cut the false rejections.

Azure AI FoundryMCPRAGLLM-as-judgeSonnet 4.6

Each agent is versioned in a registry, so a bad hand-off fails loudly instead of quietly corrupting the run.

VFX toolingLive film work

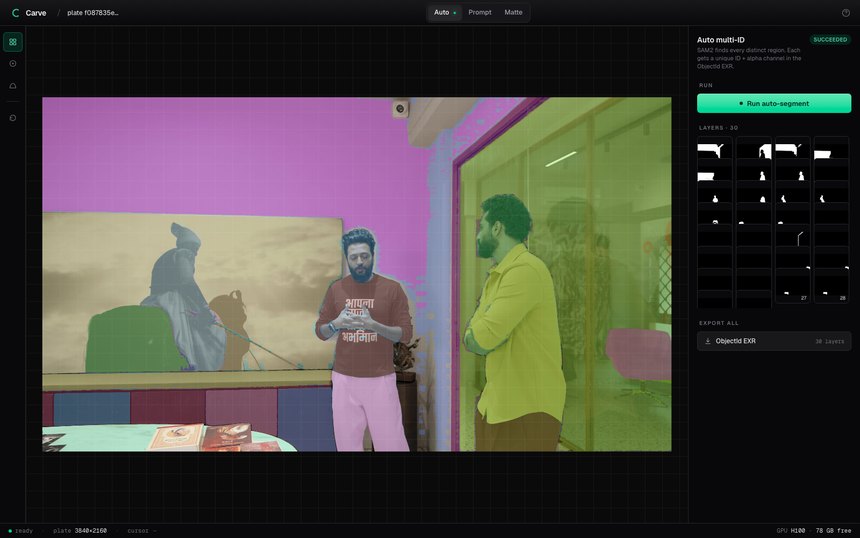
Carve

A browser tool for VFX teams: segment objects, matte hair and fur, remove anything from a shot. I A/B-tested SAM 3.1's tiled video mode against SAM 3, and it is 20x faster but only reaches 54% recall on dense crowds, so it ships for tracking up to about 100 subjects and SAM 3 stays the default for crowds. The models will not all fit in memory at once, so the backend lazy-loads and swaps one at a time.

FastAPISAM 2/3/3.1ViTMatteProPainterrepo ↗
Carve UI, auto multi-ID segmentation Auto multi-ID
Open repo ↗
Model trainingShipping

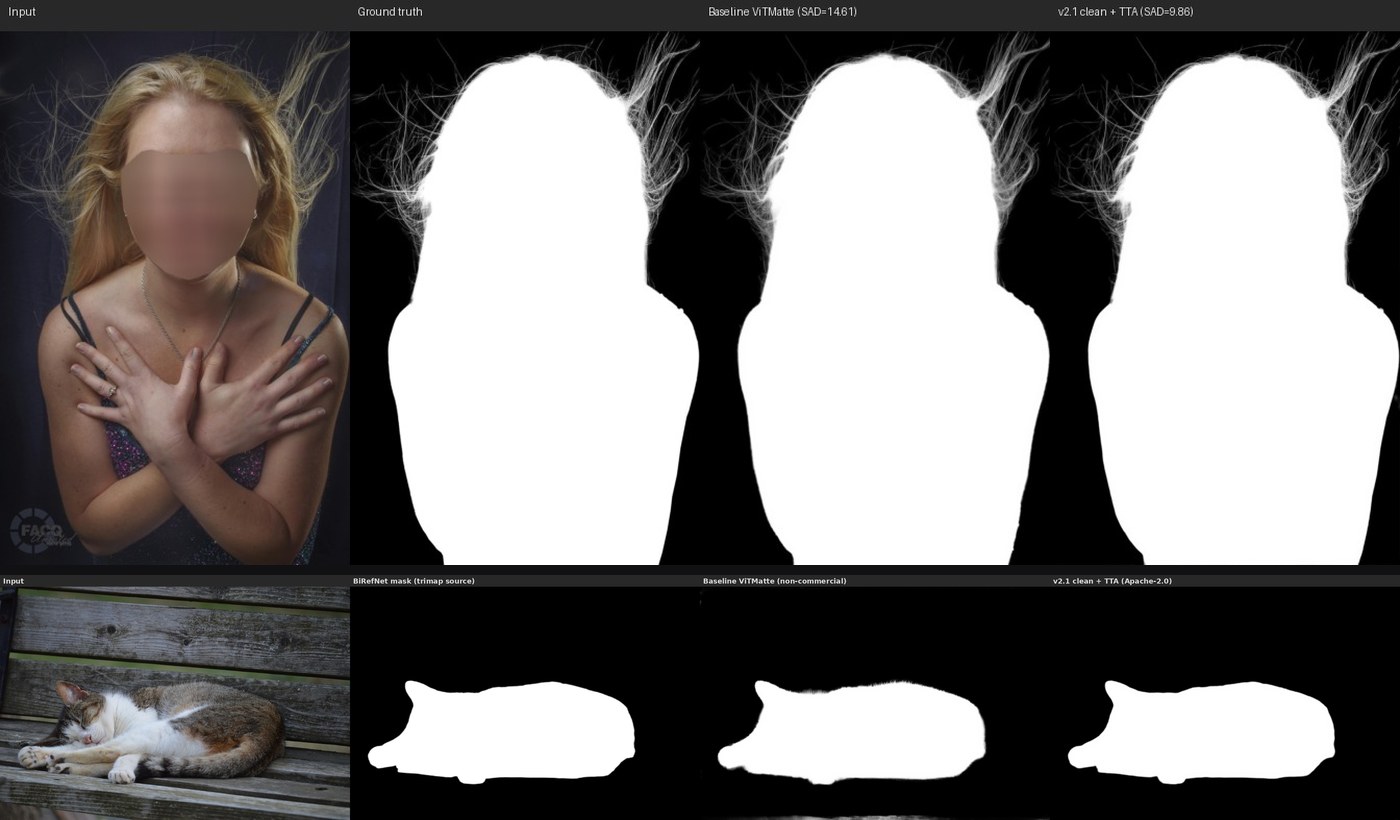
Clean-license matte model

Stock ViTMatte weights inherit a research-only licence, which blocks external client delivery. I retrained an Apache-2.0 replacement that had to beat the model it replaced, and on held-out frames it does: SAD 9.86 against 14.61, with the flyaway hair intact. The trap worth knowing is normalisation, where ImageNet against (0.5,0.5,0.5) is roughly an 8x difference in error and hides as a training bug.

PyTorchViTMatte-SBiRefNetCOCOP3M-10kCorridorKey
Matte comparison: input, ground truth, research baseline and my v2.1 on a flyaway-hair portrait and a cat, with SAD scores
Held-out frames: input, ground truth, research baseline, my v2.1. Lower SAD is better (9.86 vs 14.61); note the flyaway hair and the fur along the cat's back.
View ↗
3D worldsEnvironment ideation

Vantage

Two photos in, an explorable 3D world out: collider mesh, panorama and Gaussian splats, then any captured viewpoint re-rendered as a high-res still. Four model vendors sit behind one job-state API so a slow or failed stage retries on its own rather than sinking the whole job.

Node.jsfal.aiWorld Labs MarbleGaussian splatsgpt-image-2
An explorable generated world, fly-through.
Desktop / hardwareOpen source

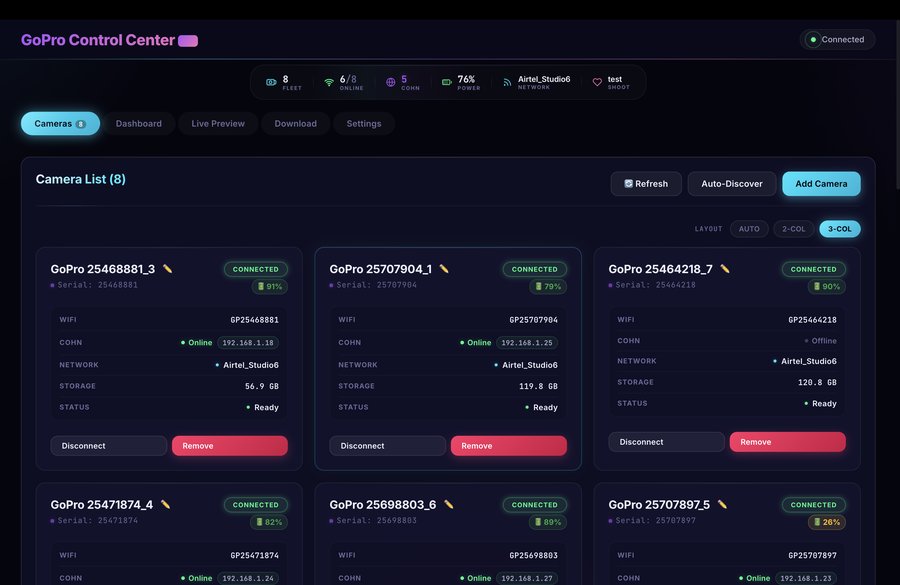
MultiCam Control

Controls a fleet of GoPros at once: BLE discovery, COHN live preview, synced record, and a parallel pull of every SD card. There is no hardware genlock on these bodies, so sync is near-simultaneous WebSocket commands corrected afterwards by embedded timecode. One codebase, installers for macOS, Windows and Linux.

ElectronReactFastAPIBLE · COHN
GoPro Control Center, camera fleet Camera fleet
Storyboard appHanuman & Krishna

Cue

Turns a screenplay into a shot-by-shot storyboard and holds every character on-model from reference sheets. It runs on hosted models with no dedicated GPU, which is what makes it cheap enough to leave running for a whole film, and the artist-facing details that mattered were export, job pause and resume, and honest progress.

Gemini 2.5gpt-image-2shot breakdowncharacter refsCPU-only
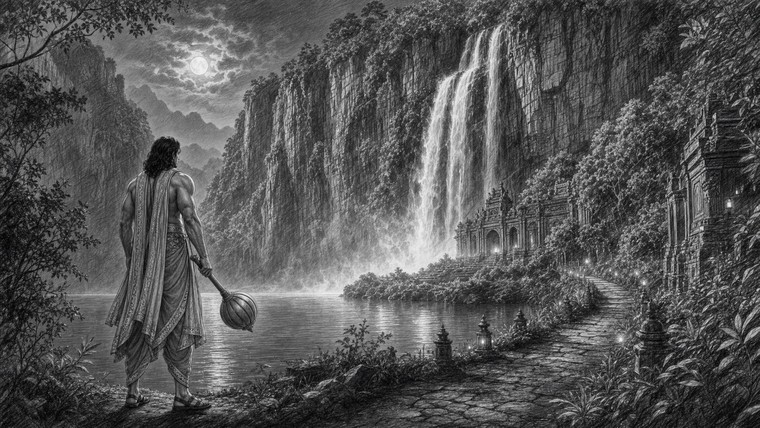
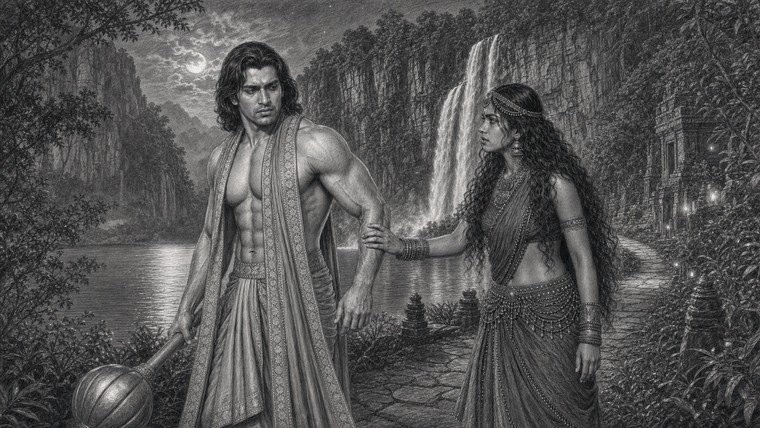
S2 E2 / EXT. FOREST - THE MOONLIT LAKE - NIGHT

"Beyond the treeline, the forest opens onto a moonlit lake fed by a crashing waterfall. Through the silver mist, a woman stands drenched beneath the falls, singing, and Bhim, mace in hand, draws back into the shadows."

Approved Bhim character reference sheet
@bhim
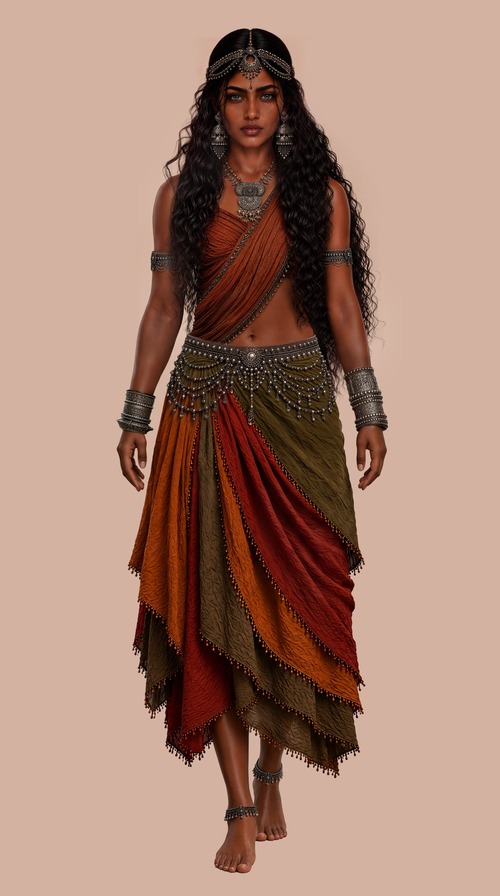
Approved Hidimba character reference sheet
@hidimba
Cue breaks the scene into shots, and every panel below holds these two on-model →
Scene storyboard, 33 shots, all generatedB&W 16:9
Storyboard shot 30, moonlit lake and waterfall, Bhim at the shoreSHOT 30XWS
@bhim
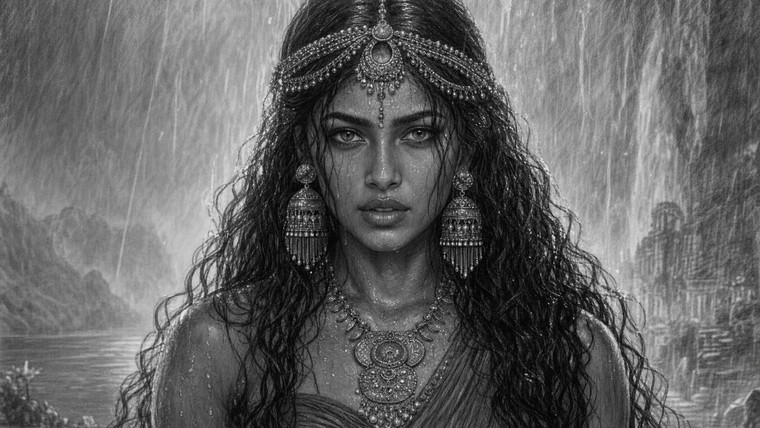
Storyboard shot 50, close-up of Hidimba beneath the fallsSHOT 50CU
@hidimba
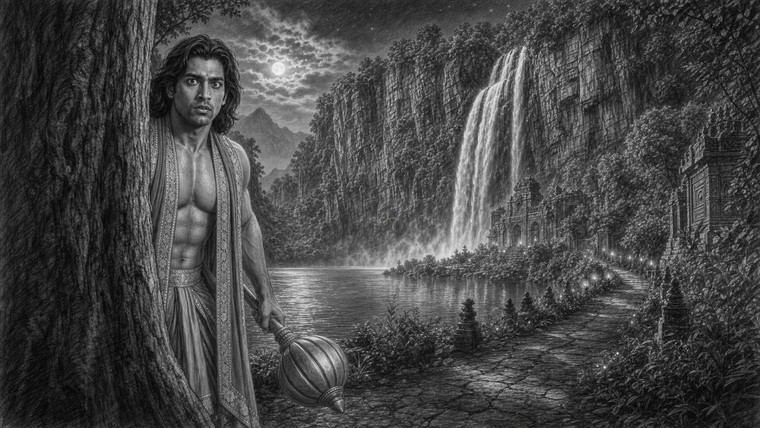
Storyboard shot 60, Bhim wary behind a treeSHOT 60MS
@bhim
Storyboard shot 90, Hidimba closerSHOT 90CU
@hidimba
Storyboard shot 130, close on BhimSHOT 130CU
@bhim
Storyboard shot 150, Bhim and Hidimba together by the lakeSHOT 150MS
@bhim @hidimba
Storyboard shot 170, Hidimba moonlitSHOT 170CU
@hidimba
Storyboard shot 300, Bhim and Hidimba by the fallsSHOT 300MS
@bhim @hidimba

Real panels from one scene Cue storyboarded end to end: all 33 shots from the screenplay. Working from just the two reference sheets above, it holds Bhim and Hidimba on-model across every panel, whatever the framing.

Agentic 3DInternal R&D

Blender Vision Agent

An agent that writes Blender Python from a photo, renders it, and scores the render against the source with a vision LLM, feeding the diff back in until the reconstruction holds up. Generate, render, verify, refine.

Blender Python APIVision LLMHeadless renderingrepo ↗
A real turntable of the agent's own reconstruction: photo in, posable 3D scene out.
Generative commerceStudio work

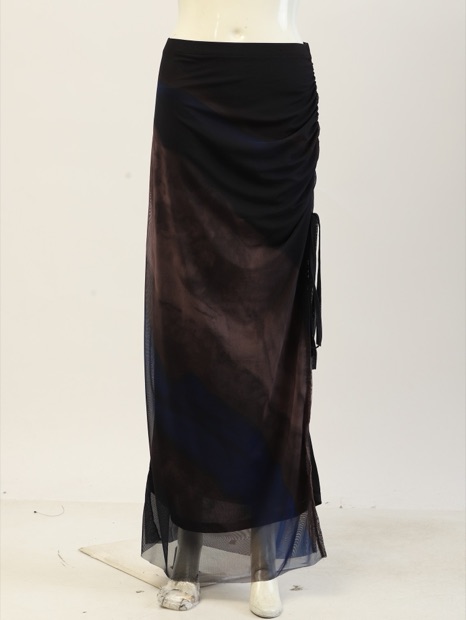
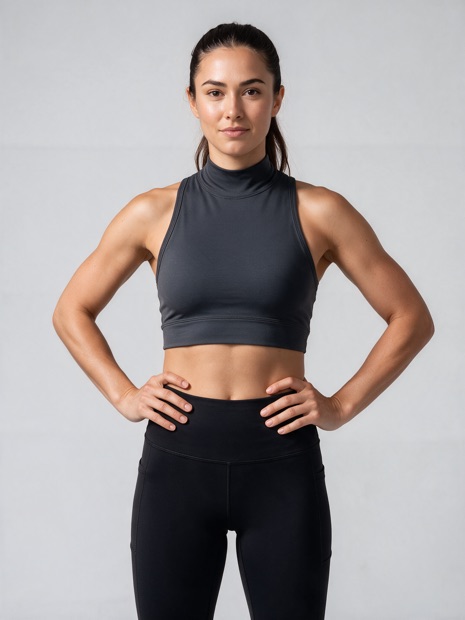
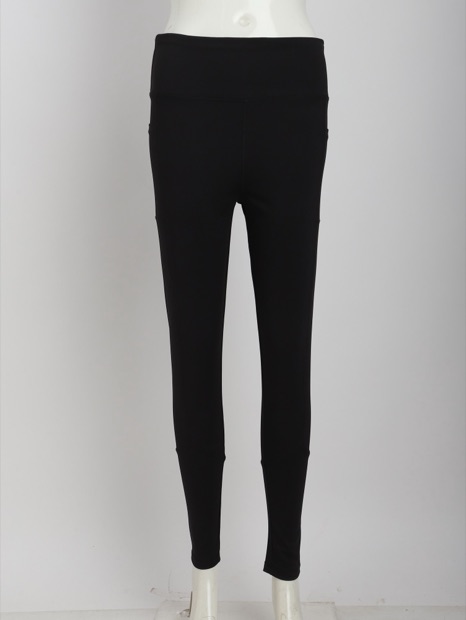
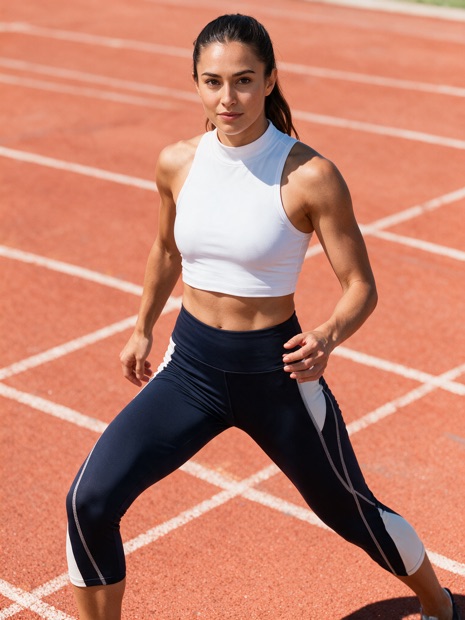
Drape

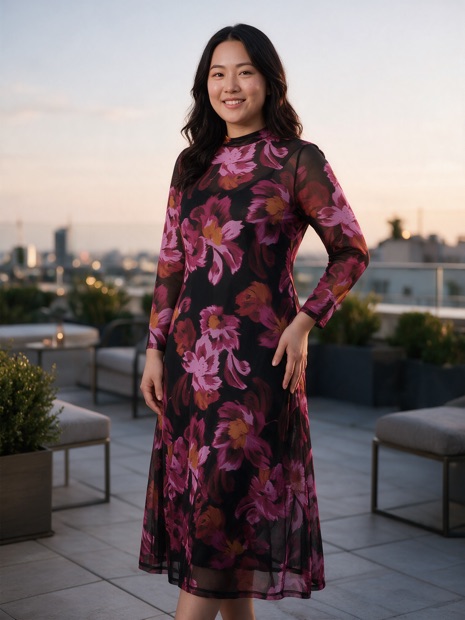
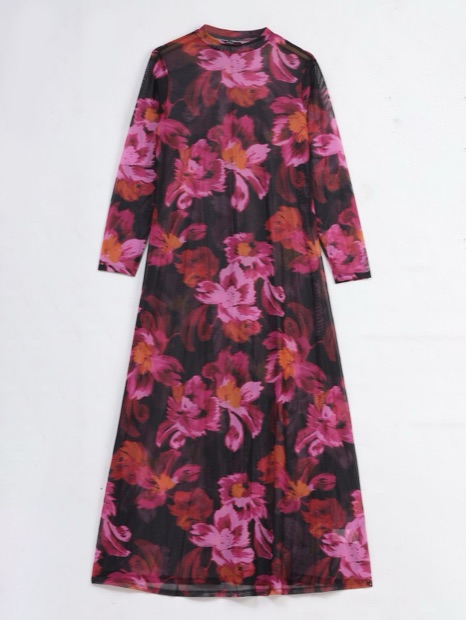
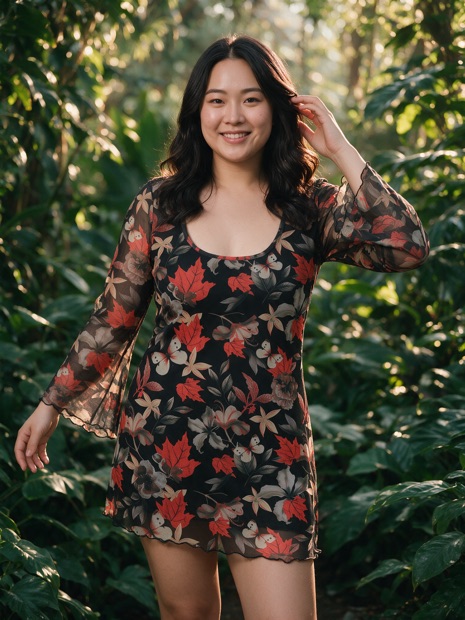
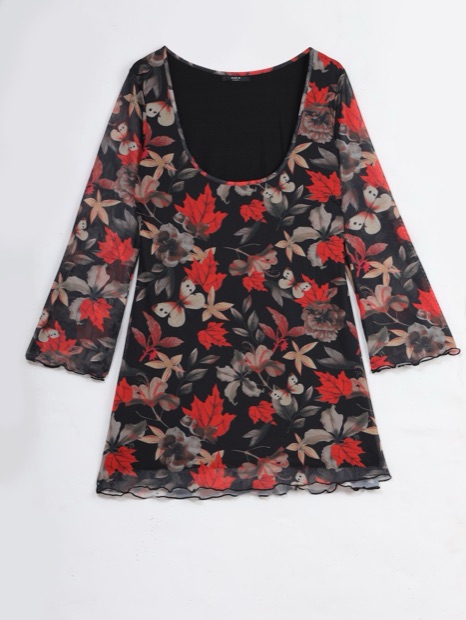
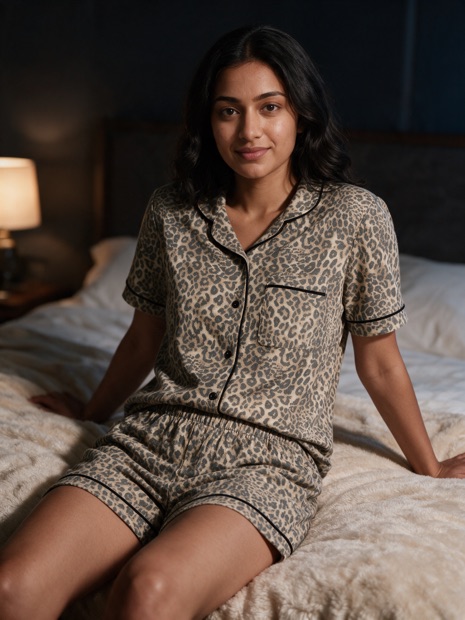
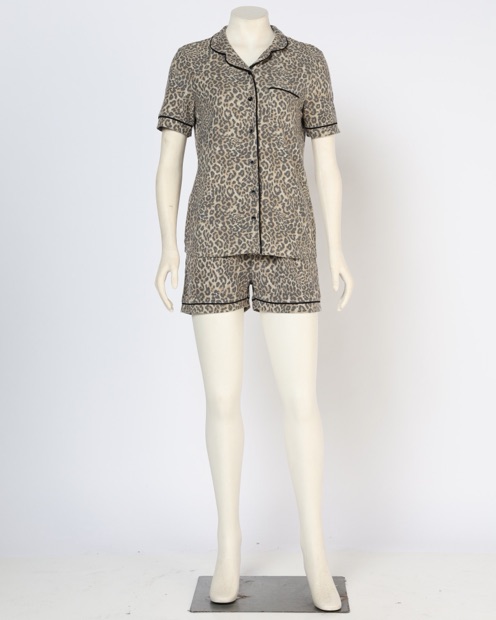
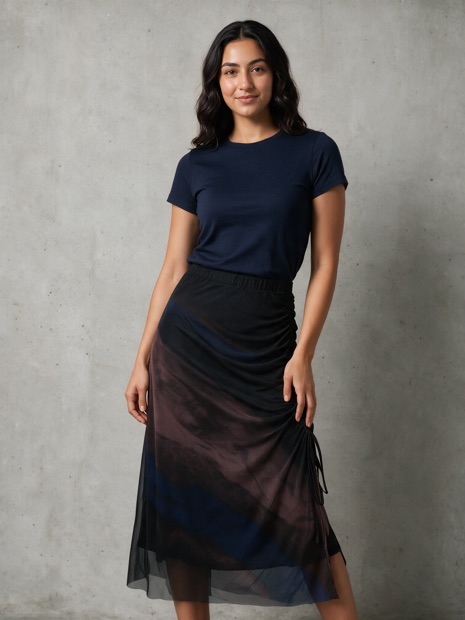
Turns flat product photography into the frames a brand would publish: the real garment, on a consistent model, with colour, print and construction held to the reference. A customer receives the actual item, so a drifted print or a shifted shade is a return, and every decision below follows from that. Analysis and art direction run as separate calls at different temperatures, fine print is cropped and upscaled into its own reference, and nothing ships until it clears a 7-point QC pass.

PythonFastAPIReactStructured vision analysisQC-gated generationrepo ↗
Generated campaign shot, floral maxi dressThe product photograph it was generated from
Generated campaign shot, printed mesh dressThe product photograph it was generated from
Generated campaign shot, leopard print pyjama setThe product photograph it was generated from
Generated campaign shot, ruched mesh skirtThe product photograph it was generated from
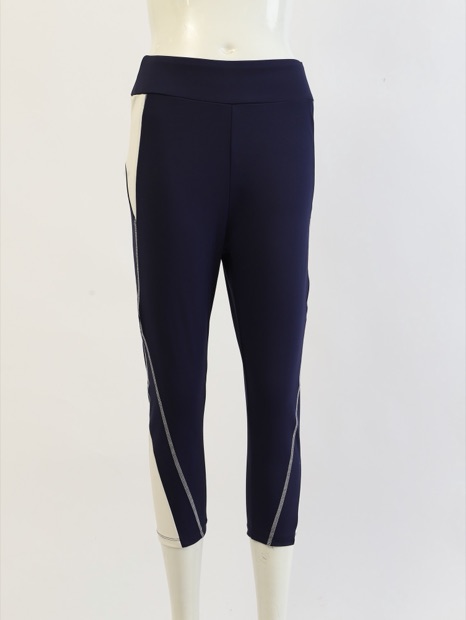
Generated campaign shot, black leggingsThe product photograph it was generated from
Generated campaign shot, navy sports leggingsThe product photograph it was generated from
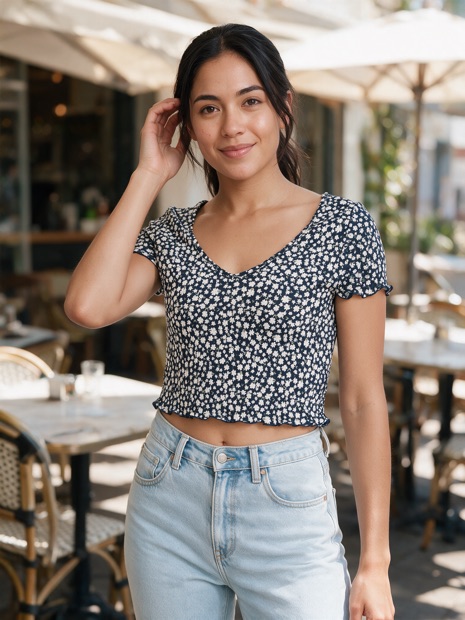
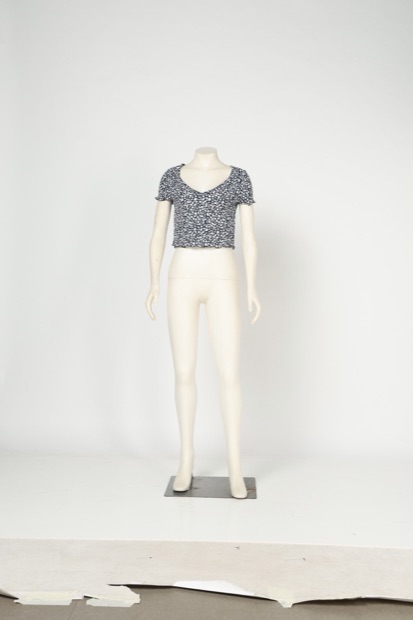
Generated campaign shot, ditsy floral topThe product photograph it was generated from
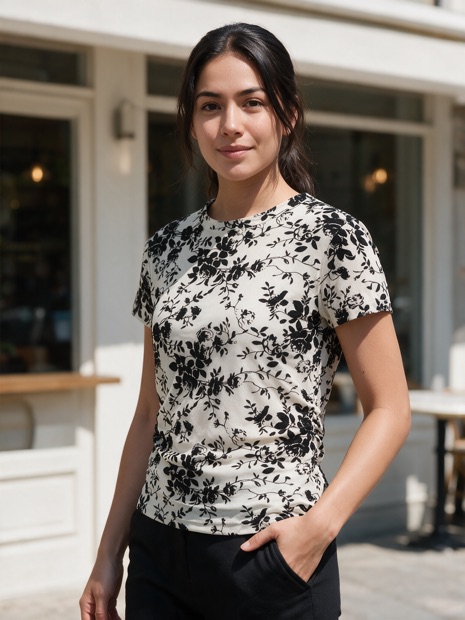
Generated campaign shot, monochrome floral teeThe product photograph it was generated from

Eight garments from one run. The inset is the product photograph that went in; the frame behind it is what came out. The model stays the same person across the whole catalogue.

Automatic QC across 56 generationspass rate
coverage & pieces
100%
avatar identity
98%
garment pattern
98%
garment structure
98%
photorealism
98%
model presence
96%
garment colour
84%

Colour is the criterion that actually fails. Everything else clears 96% or better, which is exactly why the pipeline reads colour deterministically instead of trusting one creative pass.

Audio MLStudio tooling

Speaker Voice Pipeline

Point it at a YouTube URL, a podcast, or a local file, and it isolates one speaker's voice: diarization, transcription, speaker-matching and enhancement chained into a single command. Feeds reference voices into downstream lipsync and dubbing work.

pyannoteWhisperDemucsMossFormer2Resemblyzerrepo ↗
  1. 1Downloadyt-dlp
  2. 2Diarizepyannote
  3. 3TranscribeWhisper
  4. 4Match speakerResemblyzer
  5. 5EnhanceDemucs, MossFormer2

One command: a URL in, one clean speaker's voice out.

The only audio-ML entry here. Everything else on this page is vision, video or 3D.
Generative commerceFreelance

Synthetic-UGC Ad Pipeline

Product photo in, a finished vertical ad out: a synthetic creator holds the product, talks about it, and the caption burns in, with no camera, no actor and no shoot day. Firecrawl pulls real competitor ads for the category before a script is written, so positioning is grounded rather than invented, and ElevenLabs generation and voice-matching pick a voice for the persona instead of defaulting to one stock narrator. Job state runs through a Cloudflare Durable Object per video, so a render can resume instead of restarting a multi-minute pipeline from zero.

Next.jstRPCCloudflare WorkersDurable ObjectsDrizzleElevenLabsFirecrawl
A fictional smart-bottle brand, fully generated end to end.
Same pipeline, a different persona and product; test brands throughout, no real company's likeness or IP.

Technical expertise.

Agentic AI

  • Multi-agent orchestration
  • Azure AI Foundry
  • MCP / tool calling
  • RAG · vector stores
  • LLM-as-judge evals
  • Typed agent handoff

Generative media

  • Seedance 2.0
  • Bernini
  • Flux · SDXL
  • Wan · Qwen
  • LoRA training
  • gpt-image-2 · ComfyUI

Computer vision / VFX

  • SAM 2 / 3 / 3.1
  • ViTMatte · BiRefNet
  • Segmentation
  • Soft-alpha matting
  • ProPainter clean-plate
  • EXR / ACES colour

Inference & infra

  • FastAPI serving
  • Model-swap under memory
  • systemd services
  • Cloudflare tunnels
  • Async job queues
  • Redis · PostgreSQL

3D & pipelines

  • World Labs Marble
  • Image-to-3D
  • Gaussian splats
  • Blender Python API
  • Retopo & texture bake
  • Scene generation

Backend & languages

  • Python
  • FastAPI · Node.js
  • React · Electron
  • Pipeline engineering
  • REST API design
  • Automation

Let's work together.

Available for hard, applied AI roles in generative media and production infrastructure. Fastest reply by email.

@ColinJoyL Résumé (PDF)